
Python via Java에서 프레젠테이션 정보 검색 및 업데이트
개요
Aspose.Slides는 프레젠테이션의 형식을 식별하고 전체 프레젠테이션 객체 모델을 생성하지 않고도 문서 메타데이터를 읽을 수 있습니다. 파일을 분류하거나 인벤토리를 구축하거나 프레젠테이션 콘텐츠를 로드하고 처리할지 결정하기 전에 속성을 검사해야 할 때 유용합니다.
예제는 Python용 Aspose.Slides for Java와 호환되는 Java 런타임이 필요합니다. 각 예제는 JVM이 실행 중이지 않은 경우 시작합니다. 예제에서 사용된 경로에 기존 프레젠테이션 파일을 제공하십시오.
이 문서는 PresentationFactory와 PresentationInfo를 통한 가벼운 검사를 보여주며, DocumentProperties를 통한 대상 업데이트도 설명합니다.
프레젠테이션 형식 확인
이미 로드된 프레젠테이션이 있는 경우, 로드 후 형식 감지를 위한 Determine the Original Presentation Format와 레거시 PPT, PPS, POT 스트림의 제한 사항을 확인하십시오.
파일을 읽지 않고도 PresentationFactory.getPresentationInfo로 검사하십시오. PresentationInfo.getLoadFormat 메서드는 PPTX, PPT 또는 ODP와 같은 감지된 형식을 반환합니다.
import jpype
import asposeslides

if not jpype.isJVMStarted():
    jpype.startJVM()

from asposeslides.api import LoadFormat, PresentationFactory

file_names = ["pres.pptx", "pres.ppt", "pres.odp"]

for file_name in file_names:
    presentation_info = PresentationFactory.getInstance().getPresentationInfo(file_name)
    load_format = presentation_info.getLoadFormat()
    format_name = f"Other ({load_format})"

    if load_format == LoadFormat.Pptx:
        format_name = "PPTX"
    elif load_format == LoadFormat.Ppt:
        format_name = "PPT"
    elif load_format == LoadFormat.Odp:
        format_name = "ODP"

    print(f"{file_name}: {format_name}")
경량 프레젠테이션 인벤토리 구축
많은 프레젠테이션 파일을 처리할 때, 검증, 인덱싱 또는 문서 관리 시스템을 위한 간결한 인벤토리가 필요할 수 있습니다. 이 경우 PresentationFactory.getPresentationInfo로 PresentationInfo 객체를 얻은 뒤, PresentationInfo.readDocumentProperties로 문서 메타데이터를 읽으십시오. 이 접근 방식은 Presentation 인스턴스를 생성하거나 전체 프레젠테이션 객체 모델을 탐색할 필요가 없습니다.
DocumentProperties가 노출하는 확장 속성은 다음과 같은 인벤토리 값을 제공합니다:
| 메서드 | 인벤토리 값 |
|---|---|
| getSlides | 슬라이드 총 개수. |
| getHiddenSlides | 숨김 슬라이드 개수. |
| getNotes | 노트가 포함된 슬라이드 개수. |
| getParagraphs | 사용 가능한 경우, 단락 총 개수. |
| getWords | 단어 총 개수. |
| getMultimediaClips | 오디오 및 비디오 클립 총 개수. |
다음 예제는 Presentation 객체를 생성하지 않고 이러한 값을 읽어 간결한 인벤토리를 출력합니다. 또한 getHeadingPairs와 getTitlesOfParts를 결합하여 폰트, 테마, 슬라이드 제목과 같은 콘텐츠 그룹을 표시합니다.
import jpype
import asposeslides

if not jpype.isJVMStarted():
    jpype.startJVM()

from pathlib import Path
from asposeslides.api import LoadFormat, PresentationFactory

file_path = "sample.pptx"
presentation_info = PresentationFactory.getInstance().getPresentationInfo(file_path)
document_properties = presentation_info.readDocumentProperties()

load_format = presentation_info.getLoadFormat()
format_name = f"Other ({load_format})"

if load_format == LoadFormat.Pptx:
    format_name = "PPTX"
elif load_format == LoadFormat.Ppt:
    format_name = "PPT"
elif load_format == LoadFormat.Odp:
    format_name = "ODP"

print(f"File: {Path(file_path).name}")
print(f"Format: {format_name}")
print(f"Title: {document_properties.getTitle()}")
print(f"Author: {document_properties.getAuthor()}")
print("Statistics:")
print(f"  Slides: {document_properties.getSlides()}")
print(f"  Hidden slides: {document_properties.getHiddenSlides()}")
print(f"  Slides with notes: {document_properties.getNotes()}")
print(f"  Paragraphs: {document_properties.getParagraphs()}")
print(f"  Words: {document_properties.getWords()}")
print(f"  Multimedia clips: {document_properties.getMultimediaClips()}")

heading_pairs = document_properties.getHeadingPairs()
titles_of_parts = document_properties.getTitlesOfParts()
heading_pairs = heading_pairs if heading_pairs is not None else []
titles_of_parts = titles_of_parts if titles_of_parts is not None else []
part_index = 0

if len(heading_pairs) == 0 or len(titles_of_parts) == 0:
    print("Content groups: not available")
else:
    print("Content groups:")

    for heading_pair in heading_pairs:
        print(f"  {heading_pair.getName()} ({heading_pair.getCount()})")

        for part_offset in range(heading_pair.getCount()):
            if part_index >= len(titles_of_parts):
                break
            print(f"    - {titles_of_parts[part_index]}")
            part_index += 1

    if part_index < len(titles_of_parts):
        print("  Other parts:")

        while part_index < len(titles_of_parts):
            print(f"    - {titles_of_parts[part_index]}")
            part_index += 1
각 HeadingPair은 그룹 이름과 해당 그룹의 항목 수를 제공합니다. DocumentProperties.getTitlesOfParts는 평면화된 순서 배열을 반환하므로 각 헤딩 페어가 지정한 연속 제목 개수만큼 사용하십시오.
저장된 메타데이터 및 형식 제한
PresentationInfo.readDocumentProperties로 반환된 인벤토리 속성은 원본 문서에 존재하는 메타데이터를 반영합니다. Aspose.Slides는 이 호출을 위해 프레젠테이션 객체 모델을 로드하고 순회하지 않으며, 누락된 속성은 기본값으로 표시되고, 마지막 저장 시 애플리케이션이 문서 속성을 업데이트하지 않은 경우 저장된 값이 오래될 수 있습니다.
- PPTX: 슬라이드, 노트, 숨김 슬라이드, 단락, 단어 및 멀티미디어 개수와 헤딩 페어, 파트 제목에 대한 확장 문서 속성을 제공합니다. 가용성은 문서 작성자가 어떤 속성을 기록했는지에 따라 다릅니다.
- PPT: 바이너리 형식은 해당 문서 요약 속성을 저장할 수 있습니다. 속성이 없거나 문서 작성자가 새로 고치지 않은 경우, Aspose.Slides는 슬라이드에서 계산하지 않고 저장된 값 또는 기본값을 반환합니다.
- ODP: OpenDocument 메타데이터는 페이지, 단락, 단어 개수와 같은 일반 문서 통계를 제공하지만 PowerPoint 고유의 확장 속성과는 완전히 매핑되지 않을 수 있습니다. 숨김 슬라이드, 노트 슬라이드, 멀티미디어, 헤딩 페어 및 파트 제목 메타데이터가 없을 수 있으며, 인벤토리 속성은 기본값을 반환합니다. 값이 0이거나 빈 배열이라고 해서 해당 콘텐츠가 존재하지 않는다는 권위 있는 증거로 받아들여서는 안 됩니다.
인벤토리와 초기 검사는 경량 메타데이터 접근 방식을 사용하십시오. 결과가 메모리 내 변경을 반영해야 하거나 실제 프레젠테이션 콘텐츠를 확인해야 할 경우 프레젠테이션을 로드하고 라이브 객체 모델을 검사하십시오.
프레젠테이션 속성 업데이트
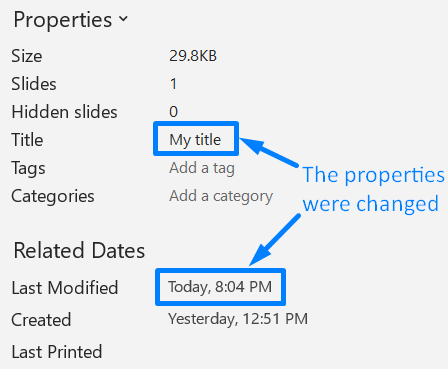
PresentationInfo.readDocumentProperties로 반환된 속성은 Presentation 인스턴스를 만들지 않고도 변경할 수 있습니다. 변경 사항은 PresentationInfo.updateDocumentProperties로 적용한 뒤, PresentationInfo.writeBindedPresentation으로 바인딩된 프레젠테이션을 기록하십시오.
다음 이미지는 원본 문서 속성을 보여줍니다.
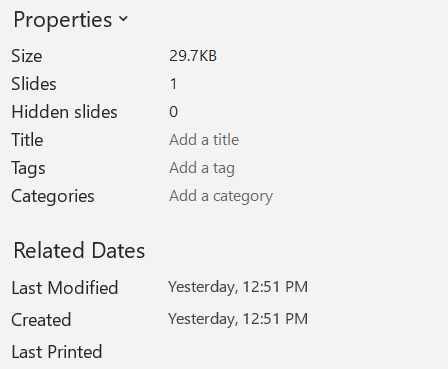
다음 예제는 제목과 마지막 저장 시간을 변경하고 결과를 새 파일에 기록합니다:
import jpype
import asposeslides

if not jpype.isJVMStarted():
    jpype.startJVM()

from asposeslides.api import PresentationFactory
from java.io import FileOutputStream
from java.util import Date

source_file = "sample.pptx"
output_file = "sample_with_updated_properties.pptx"
presentation_info = PresentationFactory.getInstance().getPresentationInfo(source_file)
document_properties = presentation_info.readDocumentProperties()

document_properties.setTitle("Quarterly sales report")
last_saved_time = Date()
document_properties.setLastSavedTime(last_saved_time)

presentation_info.updateDocumentProperties(document_properties)
output_stream = FileOutputStream(output_file)
try:
    presentation_info.writeBindedPresentation(output_stream)
finally:
    output_stream.close()
다음 이미지는 업데이트된 문서 속성을 보여줍니다.
유용한 링크
보안 검사 및 보호 설정과 관련된 내용은 다음 문서를 참고하십시오:
FAQ
폰트가 임베드되었는지 및 어떤 폰트가 임베드되었는지 어떻게 확인할 수 있나요?
프레젠테이션을 로드하고 Presentation.getFontsManager를 사용하십시오. FontsManager.getEmbeddedFonts로 임베드된 폰트를, FontsManager.getFonts로 프레젠테이션에서 사용된 폰트를 얻은 뒤 두 결과를 비교하여 렌더링에 필요하지만 임베드되지 않은 폰트를 찾으십시오.
파일에 숨김 슬라이드가 있는지와 개수를 빠르게 확인하려면 어떻게 해야 하나요?
저장된 문서 메타데이터가 충분한 경우, PresentationFactory.getPresentationInfo와 PresentationInfo.readDocumentProperties를 통해 DocumentProperties.getHiddenSlides를 읽으십시오. 이는 경량 인벤토리에 적합합니다. 메모리에서 프레젠테이션이 변경되었거나 실시간 값을 확인해야 할 경우, Presentation.getSlides를 순회하고 각 슬라이드의 Slide.getHidden 메서드를 검사하십시오.
맞춤형 슬라이드 크기와 방향이 사용되었는지, 기본값과 다른지 감지할 수 있나요?
예. 프레젠테이션을 로드하고 Presentation.getSlideSize를 호출하십시오. SlideSize.getType, SlideSize.getSize, SlideSize.getOrientation으로 현재 설정을 기대값 및 기본 차원과 비교하십시오.
차트가 외부 데이터 소스를 참조하는지 빠르게 확인할 방법이 있나요?
예. 각 Chart를 찾아 ChartData.getDataSourceType를 호출하십시오. 외부 워크북인 경우 ChartData.getExternalWorkbookPath를 호출하면 데이터 소스 유형과 경로를 통해 외부 참조를 확인할 수 있습니다. 대상이 실제로 사용 가능한지는 별도의 리소스 검사가 필요합니다.
렌더링이나 PDF 내보내기를 느리게 할 수 있는 ‘무거운’ 슬라이드를 어떻게 평가할 수 있나요?
단일 복잡도 속성은 없습니다. Presentation.getSlides와 각 슬라이드의 BaseSlide.getShapes 컬렉션을 순회하십시오. 도형 개수와 대형 이미지, 효과, 애니메이션, 멀티미디어 존재 여부를 스크리닝 신호로 사용하고, 대표적인 렌더링 또는 내보내기 시간을 측정하여 슬라이드가 실제 성능 병목인지 판단하십시오.