
ค้นหาและแทนที่ข้อความในงานนำเสนอ PowerPoint ด้วย Python ผ่าน Java
ภาพรวม
Aspose.Slides for Python via Java สามารถค้นหา, ไฮไลท์, และแทนที่ข้อความในกรอบข้อความเดี่ยวหรือทั่วทั้งการนำเสนอได้ ทุกการดำเนินการยังสามารถแจ้งให้แอปพลิเคชันทราบทุกการจับคู่ผ่านการเรียกกลับผลลัพธ์ ซึ่งทำให้สามารถอัปเดตการนำเสนอและสร้างบันทึกการตรวจสอบพร้อมกันที่ประกอบด้วยข้อความที่ตรงกัน, บริบท, ตำแหน่ง, กรอบข้อความ, และหมายเลขสไลด์
ความสามารถเหล่านี้เป็นประโยชน์สำหรับการตรวจทาน, การลบข้อมูล, การตรวจสอบคำศัพท์, การทำความสะอาดเทมเพลต, และกระบวนการทำรายงานอัตโนมัติ
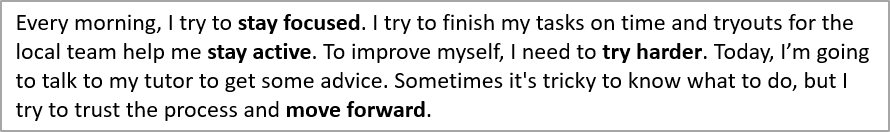
ในตัวอย่างแรกด้านล่าง เราใช้ไฟล์ชื่อ “sample.pptx” ซึ่งมีกล่องข้อความเดียวบนสไลด์แรกพร้อมข้อความต่อไปนี้:
เลือกขอบเขตการค้นหา
ใช้เมธอดบน TextFrame เพื่อจำกัดการดำเนินการให้กับกรอบข้อความหนึ่งเดียว ใช้เมธอดบน Presentation เพื่อประมวลผลข้อความทั้งหมดที่เกี่ยวข้องในงานนำเสนอ
| การดำเนินการ | กรอบข้อความหนึ่ง | งานนำเสนอทั้งหมด |
|---|---|---|
| ไฮไลท์ข้อความตามตัวอักษร | TextFrame.highlightText | Presentation.highlightText |
| ไฮไลท์ผลการจับคู่แบบ regular expression | TextFrame.highlightRegex | Presentation.highlightRegex |
| แทนที่ข้อความตามตัวอักษร | TextFrame.replaceText | Presentation.replaceText |
| แทนที่ผลการจับคู่แบบ regular expression | TextFrame.replaceRegex | Presentation.replaceRegex |
กำหนดค่าการจับข้อความ
สำหรับการดำเนินการข้อความตามตัวอักษร ให้ใช้ TextSearchOptions เพื่อควบคุมการจับคู่:
- setWholeWordsOnly จำกัดการจับคู่ให้เป็นคำเต็มเท่านั้น.
- setCaseSensitive ควบคุมว่าต้องตรงตามตัวพิมพ์ใหญ่‑เล็กหรือไม่.
- setIncludeNotes รวมโน้ตสไลด์ในการค้นหา, การแทนที่, และการไฮไลท์ระดับงานนำเสนอ.
การดำเนินการแบบนิพจน์ปกติใช้ Pattern ของ Java ดังนั้นกฎการจับคู่เช่นการแยกแยะตัวพิมพ์ใหญ่‑เล็กและขอบเขตคำจะกำหนดโดยนิพจน์และแฟล็กของมัน.
ระบุตัวเจ้าของของกรอบข้อความ
เวิร์กโฟลว์การประมวลผลข้อความทั่วไปมักได้รับ TextFrame ในขณะค้นหา, แทนที่, ตรวจสอบ, หรือส่งออกข้อความ ใช้ TextFrame.getParentShape และ TextFrame.getParentCell เพื่อระบุว่าอ็อบเจกต์งานนำเสนอใดเป็นเจ้าของกรอบข้อความนี้
ค่าที่คาดหวังขึ้นอยู่กับเจ้าของ:
| เจ้าของกรอบข้อความ | getParentShape |
getParentCell |
|---|---|---|
| AutoShape หรือรูปร่างอื่นที่มีข้อความ | The owning Shape | None |
| เซลล์ของตาราง | None |
The owning Cell |
Both methods provide read-only navigation. Calling them does not move the text frame or change its owner. Generic code should check both values for None and handle the possibility that neither owner is available.
The following example uses SlideUtil.getAllTextFrames to iterate through the text frames in a presentation. For shapes, it reports the shape name, Java runtime type, and containing slide. For table cells, it reports the zero-based column and row coordinates and the containing slide.
import jpype
import asposeslides

if not jpype.isJVMStarted():
    jpype.startJVM()

from asposeslides.api import Presentation, SaveFormat, Slide, NotesSlide, SlideUtil, TextSearchOptions

presentation = Presentation("presentation.pptx")
try:
    text_frames = SlideUtil.getAllTextFrames(presentation, False)
    for text_frame in text_frames:
        owner_shape = text_frame.getParentShape()
        owner_cell = text_frame.getParentCell()
        if owner_shape is not None:
            shape_name = str(owner_shape.getName()) or "(unnamed)"
            shape_type = owner_shape.getClass().getSimpleName()
            base_slide = owner_shape.getSlide()
        elif owner_cell is not None:
            base_slide = owner_cell.getSlide()
        else:
            print("The text frame owner is not available as a shape or table cell.")
            continue

        if isinstance(base_slide, Slide):
            slide_label = f"slide {base_slide.getSlideNumber()}"
        elif isinstance(base_slide, NotesSlide):
            slide_label = f"notes for slide {base_slide.getParentSlide().getSlideNumber()}"
        else:
            slide_label = str(base_slide.getClass().getSimpleName())

        if owner_shape is not None:
            print(f"Shape: {shape_name}; type: {shape_type}; {slide_label}")
        else:
            print(f"Table cell: column {owner_cell.getFirstColumnIndex()}, row {owner_cell.getFirstRowIndex()}; {slide_label}")
finally:
    presentation.dispose()
For SmartArt content, iterate through the shapes in SmartArtNode.getShapes and access each SmartArtShape.getTextFrame. The text frame can be traced to its associated shape through TextFrame.getParentShape, while TextFrame.getParentCell returns None. Therefore, the shape branch in the example also handles text from SmartArt nodes.
รวบรวมข้อมูลการจับคู่ด้วย Callback
Implement IFindResultCallback through jpype.JProxy to receive a notification for every match. Its foundResult method provides the related text frame, the source text, the matched text, and the match position.
The callback does not receive a slide number directly. The implementation below derives it from the parent slide and also handles text found in slide notes. An optional slide number allows the same result model to represent text associated with other slide types.
import jpype
import asposeslides

if not jpype.isJVMStarted():
    jpype.startJVM()

from asposeslides.api import Presentation, SaveFormat, Slide, NotesSlide, SlideUtil, TextSearchOptions

class TextMatch:
    def __init__(self, text_frame, source_text, found_text, text_position, slide_number):
        self.text_frame = text_frame
        self.source_text = source_text
        self.found_text = found_text
        self.text_position = text_position
        self.slide_number = slide_number


class TextSearchCallback:
    def __init__(self):
        self.results = []

    def foundResult(self, text_frame, source_text, found_text, text_position):
        parent_shape = text_frame.getParentShape()
        parent_cell = text_frame.getParentCell()
        if parent_shape is not None:
            parent_slide = parent_shape.getSlide()
        elif parent_cell is not None:
            parent_slide = parent_cell.getSlide()
        else:
            parent_slide = text_frame.getSlide()

        slide_number = None
        if isinstance(parent_slide, Slide):
            slide_number = parent_slide.getSlideNumber()
        elif isinstance(parent_slide, NotesSlide):
            slide_number = parent_slide.getParentSlide().getSlideNumber()

        result = TextMatch(text_frame, str(source_text), str(found_text), text_position, slide_number)
        self.results.append(result)
For replacement operations, found_text contains the original matched text, so the callback can record exactly which terms were replaced.
ไฮไลท์ข้อความ
Use the TextFrame.highlightText method to highlight literal-text matches in a text frame. Pass TextSearchOptions to control the search and a callback to collect match details.
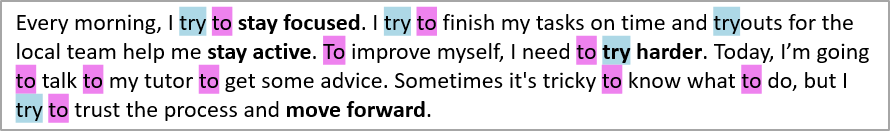
The code example below highlights all occurrences of the characters “try” and then highlights only the complete word “to”. Both searches report their matches to the same callback.
import jpype
import asposeslides

if not jpype.isJVMStarted():
    jpype.startJVM()

from asposeslides.api import Presentation, SaveFormat, Slide, NotesSlide, SlideUtil, TextSearchOptions

Color = jpype.JClass("java.awt.Color")
Pattern = jpype.JClass("java.util.regex.Pattern")

class TextMatch:
    def __init__(self, text_frame, source_text, found_text, text_position, slide_number):
        self.text_frame = text_frame
        self.source_text = source_text
        self.found_text = found_text
        self.text_position = text_position
        self.slide_number = slide_number


class TextSearchCallback:
    def __init__(self):
        self.results = []

    def foundResult(self, text_frame, source_text, found_text, text_position):
        parent_shape = text_frame.getParentShape()
        parent_cell = text_frame.getParentCell()
        if parent_shape is not None:
            parent_slide = parent_shape.getSlide()
        elif parent_cell is not None:
            parent_slide = parent_cell.getSlide()
        else:
            parent_slide = text_frame.getSlide()

        slide_number = None
        if isinstance(parent_slide, Slide):
            slide_number = parent_slide.getSlideNumber()
        elif isinstance(parent_slide, NotesSlide):
            slide_number = parent_slide.getParentSlide().getSlideNumber()

        result = TextMatch(text_frame, str(source_text), str(found_text), text_position, slide_number)
        self.results.append(result)


presentation = Presentation("sample.pptx")
try:
    slide = presentation.getSlides().get_Item(0)
    shape = slide.getShapes().get_Item(0)
    callback_handler = TextSearchCallback()
    callback = jpype.JProxy("com.aspose.slides.IFindResultCallback", inst=callback_handler)

    substring_search_options = TextSearchOptions()
    substring_search_options.setCaseSensitive(False)
    substring_highlight_color = Color(173, 216, 230)

    # ไฮไลท์ทุกการเกิดของ "try" ในกรอบข้อความ.
    shape.getTextFrame().highlightText("try", substring_highlight_color, substring_search_options, callback)

    whole_word_search_options = TextSearchOptions()
    whole_word_search_options.setWholeWordsOnly(True)
    whole_word_search_options.setCaseSensitive(False)
    whole_word_highlight_color = Color(238, 130, 238)

    # ไฮไลท์เฉพาะคำเต็ม "to".
    shape.getTextFrame().highlightText("to", whole_word_highlight_color, whole_word_search_options, callback)

    for result in callback_handler.results:
        print(f"Found '{result.found_text}' at position {result.text_position} on slide {result.slide_number}.")

    presentation.save("highlighted_text.pptx", SaveFormat.Pptx)
finally:
    presentation.dispose()
ผลลัพธ์:
ไฮไลท์ข้อความโดยใช้ Regular Expressions
The TextFrame.highlightRegex method highlights text matches found by a regular expression in a text frame.
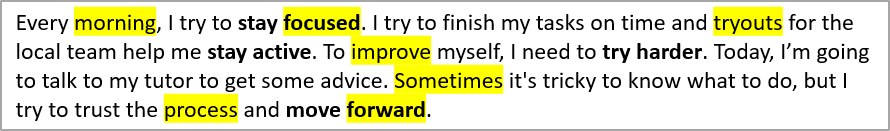
The following code highlights all words containing seven or more characters and collects each match:
import jpype
import asposeslides

if not jpype.isJVMStarted():
    jpype.startJVM()

from asposeslides.api import Presentation, SaveFormat, Slide, NotesSlide, SlideUtil, TextSearchOptions

Color = jpype.JClass("java.awt.Color")
Pattern = jpype.JClass("java.util.regex.Pattern")

class TextMatch:
    def __init__(self, text_frame, source_text, found_text, text_position, slide_number):
        self.text_frame = text_frame
        self.source_text = source_text
        self.found_text = found_text
        self.text_position = text_position
        self.slide_number = slide_number


class TextSearchCallback:
    def __init__(self):
        self.results = []

    def foundResult(self, text_frame, source_text, found_text, text_position):
        parent_shape = text_frame.getParentShape()
        parent_cell = text_frame.getParentCell()
        if parent_shape is not None:
            parent_slide = parent_shape.getSlide()
        elif parent_cell is not None:
            parent_slide = parent_cell.getSlide()
        else:
            parent_slide = text_frame.getSlide()

        slide_number = None
        if isinstance(parent_slide, Slide):
            slide_number = parent_slide.getSlideNumber()
        elif isinstance(parent_slide, NotesSlide):
            slide_number = parent_slide.getParentSlide().getSlideNumber()

        result = TextMatch(text_frame, str(source_text), str(found_text), text_position, slide_number)
        self.results.append(result)


presentation = Presentation("sample.pptx")
try:
    slide = presentation.getSlides().get_Item(0)
    shape = slide.getShapes().get_Item(0)
    callback_handler = TextSearchCallback()
    callback = jpype.JProxy("com.aspose.slides.IFindResultCallback", inst=callback_handler)
    regex = Pattern.compile("\\b[^\\s]{7,}\\b")

    shape.getTextFrame().highlightRegex(regex, Color.YELLOW, callback)

    presentation.save("highlighted_text_using_regex.pptx", SaveFormat.Pptx)
finally:
    presentation.dispose()
ผลลัพธ์:
ไฮไลท์ข้อความทั่วทั้งงานนำเสนอ
Use Presentation.highlightText and Presentation.highlightRegex to search all applicable text frames in a presentation. The following example highlights a literal term and all email addresses while keeping separate result collections for the two searches.
import jpype
import asposeslides

if not jpype.isJVMStarted():
    jpype.startJVM()

from asposeslides.api import Presentation, SaveFormat, Slide, NotesSlide, SlideUtil, TextSearchOptions

Color = jpype.JClass("java.awt.Color")
Pattern = jpype.JClass("java.util.regex.Pattern")

class TextMatch:
    def __init__(self, text_frame, source_text, found_text, text_position, slide_number):
        self.text_frame = text_frame
        self.source_text = source_text
        self.found_text = found_text
        self.text_position = text_position
        self.slide_number = slide_number


class TextSearchCallback:
    def __init__(self):
        self.results = []

    def foundResult(self, text_frame, source_text, found_text, text_position):
        parent_shape = text_frame.getParentShape()
        parent_cell = text_frame.getParentCell()
        if parent_shape is not None:
            parent_slide = parent_shape.getSlide()
        elif parent_cell is not None:
            parent_slide = parent_cell.getSlide()
        else:
            parent_slide = text_frame.getSlide()

        slide_number = None
        if isinstance(parent_slide, Slide):
            slide_number = parent_slide.getSlideNumber()
        elif isinstance(parent_slide, NotesSlide):
            slide_number = parent_slide.getParentSlide().getSlideNumber()

        result = TextMatch(text_frame, str(source_text), str(found_text), text_position, slide_number)
        self.results.append(result)


presentation = Presentation("presentation.pptx")
try:
    term_callback_handler = TextSearchCallback()
    term_callback = jpype.JProxy("com.aspose.slides.IFindResultCallback", inst=term_callback_handler)
    search_options = TextSearchOptions()
    search_options.setWholeWordsOnly(True)
    search_options.setCaseSensitive(False)

    presentation.highlightText("confidential", Color.ORANGE, search_options, term_callback)

    email_callback_handler = TextSearchCallback()
    email_callback = jpype.JProxy("com.aspose.slides.IFindResultCallback", inst=email_callback_handler)
    email_regex = Pattern.compile("\\b[A-Z0-9._%+-]+@[A-Z0-9.-]+\\.[A-Z]{2,}\\b", Pattern.CASE_INSENSITIVE)

    presentation.highlightRegex(email_regex, Color.YELLOW, email_callback)
    presentation.save("highlighted_presentation.pptx", SaveFormat.Pptx)
finally:
    presentation.dispose()
แทนที่ข้อความในกรอบข้อความ
Use TextFrame.replaceText for literal text and TextFrame.replaceRegex for pattern-based replacement. These methods update matched text within the existing text frame, which retains the surrounding portion formatting instead of rebuilding the text frame from a plain string.
The following example standardizes a spelling variant and then replaces version labels. The same callback records the original terms matched by both operations.
import jpype
import asposeslides

if not jpype.isJVMStarted():
    jpype.startJVM()

from asposeslides.api import Presentation, SaveFormat, Slide, NotesSlide, SlideUtil, TextSearchOptions

Color = jpype.JClass("java.awt.Color")
Pattern = jpype.JClass("java.util.regex.Pattern")

class TextMatch:
    def __init__(self, text_frame, source_text, found_text, text_position, slide_number):
        self.text_frame = text_frame
        self.source_text = source_text
        self.found_text = found_text
        self.text_position = text_position
        self.slide_number = slide_number


class TextSearchCallback:
    def __init__(self):
        self.results = []

    def foundResult(self, text_frame, source_text, found_text, text_position):
        parent_shape = text_frame.getParentShape()
        parent_cell = text_frame.getParentCell()
        if parent_shape is not None:
            parent_slide = parent_shape.getSlide()
        elif parent_cell is not None:
            parent_slide = parent_cell.getSlide()
        else:
            parent_slide = text_frame.getSlide()

        slide_number = None
        if isinstance(parent_slide, Slide):
            slide_number = parent_slide.getSlideNumber()
        elif isinstance(parent_slide, NotesSlide):
            slide_number = parent_slide.getParentSlide().getSlideNumber()

        result = TextMatch(text_frame, str(source_text), str(found_text), text_position, slide_number)
        self.results.append(result)


presentation = Presentation("presentation.pptx")
try:
    slide = presentation.getSlides().get_Item(0)
    shape = slide.getShapes().get_Item(0)
    callback_handler = TextSearchCallback()
    callback = jpype.JProxy("com.aspose.slides.IFindResultCallback", inst=callback_handler)
    search_options = TextSearchOptions()
    search_options.setWholeWordsOnly(True)
    search_options.setCaseSensitive(False)

    shape.getTextFrame().replaceText("colour", "color", search_options, callback)

    version_regex = Pattern.compile("\\bv\\d+(?:\\.\\d+)*\\b", Pattern.CASE_INSENSITIVE)
    shape.getTextFrame().replaceRegex(version_regex, "current version", callback)

    presentation.save("updated_text_frame.pptx", SaveFormat.Pptx)
finally:
    presentation.dispose()
If one match spans portions with different formatting, review the output to confirm which formatting should apply to the replacement text.
แทนที่ข้อความทั่วทั้งงานนำเสนอ
Use Presentation.replaceText and Presentation.replaceRegex to apply the same operations across the presentation. This is useful for template cleanup, terminology updates, and redaction.
import jpype
import asposeslides

if not jpype.isJVMStarted():
    jpype.startJVM()

from asposeslides.api import Presentation, SaveFormat, Slide, NotesSlide, SlideUtil, TextSearchOptions

Color = jpype.JClass("java.awt.Color")
Pattern = jpype.JClass("java.util.regex.Pattern")

class TextMatch:
    def __init__(self, text_frame, source_text, found_text, text_position, slide_number):
        self.text_frame = text_frame
        self.source_text = source_text
        self.found_text = found_text
        self.text_position = text_position
        self.slide_number = slide_number


class TextSearchCallback:
    def __init__(self):
        self.results = []

    def foundResult(self, text_frame, source_text, found_text, text_position):
        parent_shape = text_frame.getParentShape()
        parent_cell = text_frame.getParentCell()
        if parent_shape is not None:
            parent_slide = parent_shape.getSlide()
        elif parent_cell is not None:
            parent_slide = parent_cell.getSlide()
        else:
            parent_slide = text_frame.getSlide()

        slide_number = None
        if isinstance(parent_slide, Slide):
            slide_number = parent_slide.getSlideNumber()
        elif isinstance(parent_slide, NotesSlide):
            slide_number = parent_slide.getParentSlide().getSlideNumber()

        result = TextMatch(text_frame, str(source_text), str(found_text), text_position, slide_number)
        self.results.append(result)


presentation = Presentation("presentation.pptx")
try:
    callback_handler = TextSearchCallback()
    callback = jpype.JProxy("com.aspose.slides.IFindResultCallback", inst=callback_handler)
    search_options = TextSearchOptions()
    search_options.setWholeWordsOnly(True)
    search_options.setCaseSensitive(True)

    presentation.replaceText("Contoso", "Example Corp", search_options, callback)

    account_number_regex = Pattern.compile("\\bACCT-\\d{6}\\b")
    presentation.replaceRegex(account_number_regex, "ACCT-REDACTED", callback)

    presentation.save("updated_presentation.pptx", SaveFormat.Pptx)
finally:
    presentation.dispose()
จัดกลุ่มผลการจับคู่สำหรับการรายงาน
Because every result stores its slide number and text frame, applications can group matches for audit, reporting, or review workflows. The following example groups the collected results first by slide and then by text frame:
import jpype
import asposeslides

if not jpype.isJVMStarted():
    jpype.startJVM()

from asposeslides.api import Presentation, SaveFormat, Slide, NotesSlide, SlideUtil, TextSearchOptions

Color = jpype.JClass("java.awt.Color")
Pattern = jpype.JClass("java.util.regex.Pattern")

class TextMatch:
    def __init__(self, text_frame, source_text, found_text, text_position, slide_number):
        self.text_frame = text_frame
        self.source_text = source_text
        self.found_text = found_text
        self.text_position = text_position
        self.slide_number = slide_number


class TextSearchCallback:
    def __init__(self):
        self.results = []

    def foundResult(self, text_frame, source_text, found_text, text_position):
        parent_shape = text_frame.getParentShape()
        parent_cell = text_frame.getParentCell()
        if parent_shape is not None:
            parent_slide = parent_shape.getSlide()
        elif parent_cell is not None:
            parent_slide = parent_cell.getSlide()
        else:
            parent_slide = text_frame.getSlide()

        slide_number = None
        if isinstance(parent_slide, Slide):
            slide_number = parent_slide.getSlideNumber()
        elif isinstance(parent_slide, NotesSlide):
            slide_number = parent_slide.getParentSlide().getSlideNumber()

        result = TextMatch(text_frame, str(source_text), str(found_text), text_position, slide_number)
        self.results.append(result)


presentation = Presentation("presentation.pptx")
try:
    callback_handler = TextSearchCallback()
    callback = jpype.JProxy("com.aspose.slides.IFindResultCallback", inst=callback_handler)
    search_options = TextSearchOptions()
    search_options.setWholeWordsOnly(True)
    search_options.setCaseSensitive(True)

    presentation.replaceText("Contoso", "Example Corp", search_options, callback)

    account_number_regex = Pattern.compile("\\bACCT-\\d{6}\\b")
    presentation.replaceRegex(account_number_regex, "ACCT-REDACTED", callback)

    presentation.save("updated_presentation.pptx", SaveFormat.Pptx)
    matches_by_slide = {}
    for result in callback_handler.results:
        matches_by_text_frame = matches_by_slide.setdefault(result.slide_number, {})
        text_frame_matches = matches_by_text_frame.setdefault(result.text_frame, [])
        text_frame_matches.append(result)

    for slide_number, matches_by_text_frame in matches_by_slide.items():
        slide_label = "Other" if slide_number is None else str(slide_number)
        print(f"Slide: {slide_label}")
        for text_frame, results in matches_by_text_frame.items():
            print(f"  Text frame: {text_frame.getText()}")
            for result in results:
                print(f"    '{result.found_text}' at position {result.text_position}; context: '{result.source_text}'")
finally:
    presentation.dispose()
คำถามที่พบบ่อย
ฉันจะค้นหาเพียงกล่องข้อความเดียวแทนที่จะค้นหาทั้งงานนำเสนอได้อย่างไร?
Get the shape’s text frame and call TextFrame.highlightText, TextFrame.highlightRegex, TextFrame.replaceText, or TextFrame.replaceRegex on that text frame. Presentation-level methods process all applicable text frames instead.
ฉันจะจับคู่คำเต็มพร้อมการใช้ตัวอักษรใหญ่‑เล็กที่ถูกต้องได้อย่างไร?
Set TextSearchOptions.setWholeWordsOnly and TextSearchOptions.setCaseSensitive to True, and pass the options to a literal-text highlighting or replacement method. For regular expressions, define word boundaries and case sensitivity in the Java Pattern itself.
การค้นหาและการแทนที่สามารถรวมข้อความในโน้ตสไลด์ได้หรือไม่?
Yes. Set TextSearchOptions.setIncludeNotes to True when using a presentation-level literal-text operation. The callback implementation shown above maps a match in a notes slide back to its parent slide number.
ฉันจะสร้างรายงานโดยไม่ต้องสแกนงานนำเสนอครั้งที่สองได้อย่างไร?
Pass an IFindResultCallback implementation to the highlighting or replacement operation. The callback receives every match while the operation runs, so the application can store the source text, matched text, position, text frame, and derived slide number for later grouping or export.
การแทนที่ข้อความทำให้การจัดรูปแบบคงอยู่หรือไม่?
TextFrame.replaceText and TextFrame.replaceRegex modify matched text within the existing text frame and retain the surrounding portion formatting. If a match spans portions with different formatting, inspect the result to ensure the replacement uses the desired style.